The hardware desk / DVIDIA × OWterminal
Your hardware.A place to begin. Find a machine for an open model. Connect a camera for a useful demonstration.
Record here Phone & browser camerasRun locally Model reports & setup guidesComing next Connect as an inference provider8 16 community-reported setups · snapshot 2026-09-21. This is a research catalog; these machines are not a live fleet available to rent.
8 hardware entries
Product family pictured · exact reported configuration unverified Apple / Unified memory
M4 Pro
Reported memory Capacity not reported
Setup path MLX / Metal Explore 4 model reports How to use this hardware Check your Mac’s chip and unified memory in About This Mac. Choose an Apple Silicon runtime and a model build it supports. Compare the report’s memory and context with your configuration, then try your own task. MLX setup guide Product family pictured · exact reported configuration unverified Apple / Unified memory
M5 Max
Reported memory Capacity not reported
Setup path MLX / Metal Explore 1 model report How to use this hardware Check your Mac’s chip and unified memory in About This Mac. Choose an Apple Silicon runtime and a model build it supports. Compare the report’s memory and context with your configuration, then try your own task. MLX setup guide Two Spark units pictured · matches reported configuration NVIDIA / Desktop AI system
2× DGX Spark
Reported memory Capacity not reported
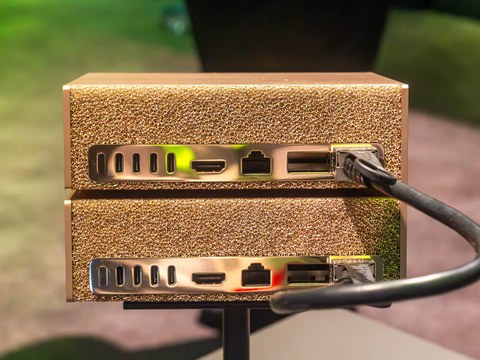
Setup path Spark-compatible runtime Explore 2 model reports How to use this hardware Follow NVIDIA’s setup playbook for your Spark and chosen runtime. Check the model build and runtime support for the machine’s architecture. These reports use two Spark units. A single unit is a different configuration. NVIDIA Spark playbooks RTX 4090 pictured as a GPU reference · this model differs NVIDIA / Discrete GPU
RTX 5090 32GB
Reported memory 32 GB VRAM
Setup path CUDA-compatible runtime Explore 2 model reports How to use this hardware Check the exact GPU, available VRAM and NVIDIA driver on your computer. Use a runtime build that supports your GPU and a compatible model format. Start with a build that fits your memory. Larger context and CPU offload change performance. llama.cpp setup guide RTX 4090 pictured · board designs vary NVIDIA / Discrete GPU
RTX 4090 24GB
Reported memory 24 GB VRAM
Setup path CUDA-compatible runtime Explore 1 model report How to use this hardware Check the exact GPU, available VRAM and NVIDIA driver on your computer. Use a runtime build that supports your GPU and a compatible model format. Start with a build that fits your memory. Larger context and CPU offload change performance. llama.cpp setup guide RTX 4090 pictured as a GPU reference · this model differs NVIDIA / Discrete GPU
RTX 5060 Ti 16GB
Reported memory 16 GB VRAM
Setup path CUDA-compatible runtime Explore 4 model reports How to use this hardware Check the exact GPU, available VRAM and NVIDIA driver on your computer. Use a runtime build that supports your GPU and a compatible model format. Start with a build that fits your memory. Larger context and CPU offload change performance. llama.cpp setup guide RTX 4090 pictured as a GPU reference · this model differs NVIDIA / Discrete GPU
RTX 3060 12GB
Reported memory 12 GB VRAM
Setup path CUDA-compatible runtime Explore 1 model report How to use this hardware Check the exact GPU, available VRAM and NVIDIA driver on your computer. Use a runtime build that supports your GPU and a compatible model format. Start with a build that fits your memory. Larger context and CPU offload change performance. llama.cpp setup guide RTX 4090 pictured as a GPU reference · this model differs NVIDIA / Discrete GPU
GTX 1660 SUPER 6GB
Reported memory 6 GB VRAM + 40 GB RAM
Setup path CUDA-compatible runtime Explore 1 model report How to use this hardware Check the exact GPU, available VRAM and NVIDIA driver on your computer. Use a runtime build that supports your GPU and a compatible model format. Start with a build that fits your memory. Larger context and CPU offload change performance. llama.cpp setup guide A report shows what someone ran on a specific setup. Check the exact model build, memory, operating system and runtime before downloading or buying. DVIDIA has not reproduced these reports.
Want to connect compute to DVIDIA? Provider onboarding is in development. You can research hardware and run models locally now; connecting a machine to paid network requests is not available yet.
Explore inference